.com 
cacheseal.com
A premium security identity for protecting, verifying and governing the high-value cache state behind modern AI inference.
ai
View listing
Home / Domains / phantominference.com
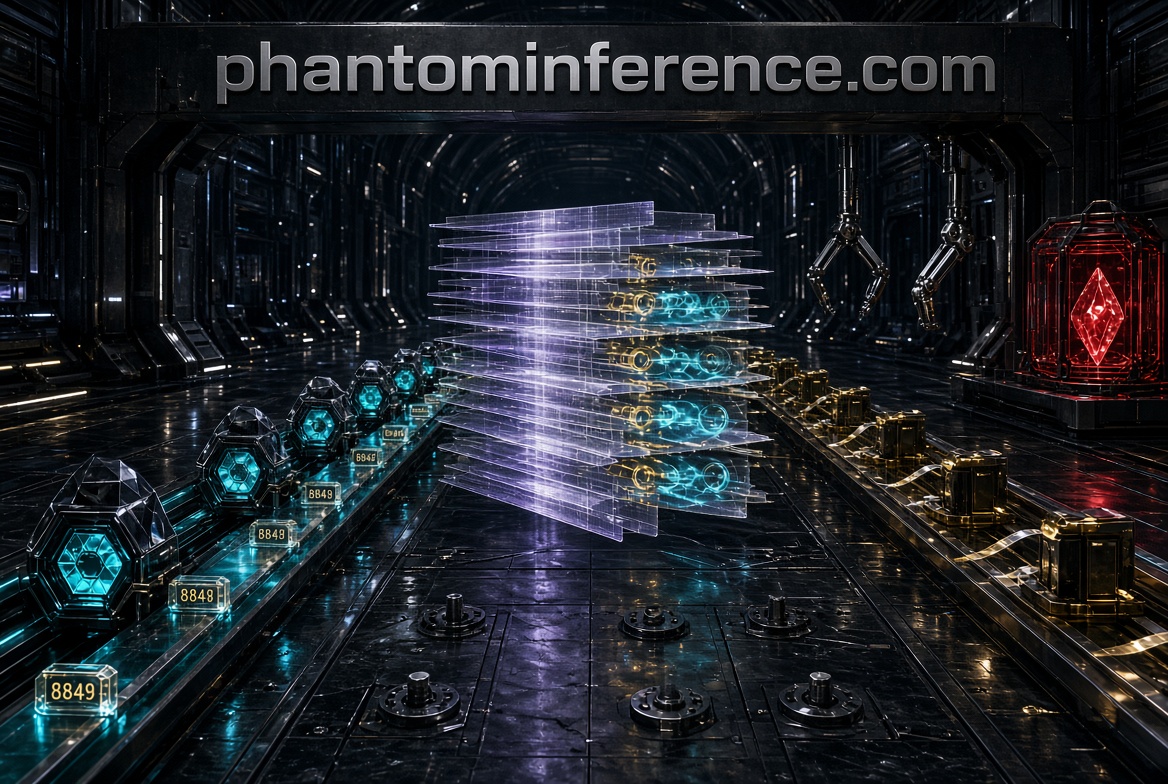
The invisible intelligence layer between a model and the world. A premium identity for the infrastructure that serves, routes, accelerates, and scales AI inference.
One message opens the conversation — availability, price, and how the transfer works.
Inquire on WhatsAppPrivate conversation. No account, no public bidding.
Prefer a form? Send a message
About this name
Users see an AI application. They do not see the infrastructure that transforms a request into an answer.
Behind every production inference request are layers of model loading, request routing, batching, caching, GPU scheduling, memory management, token generation, telemetry, scaling, and response delivery.
PhantomInference names that hidden intelligence layer.
User, agent, application, or system initiates an inference task.
Traffic is directed toward the appropriate model and compute resource.
The model transforms context into tokens, predictions, classifications, or decisions.
Systems continuously balance latency, throughput, utilization, and cost.
Intelligence returns to the application as a usable response or action.
A powerful positioning platform for the infrastructure that remains invisible while intelligent systems operate at scale.
Direct requests according to model, capacity, latency, policy, or economics.
Operate trained models continuously behind reliable production endpoints.
Optimize accelerators, memory, batching, concurrency, and distributed execution.
Deliver low-latency intelligence to applications where response time matters.
Support repeated reasoning, tool use, planning, and autonomous execution.
Extend model execution across nodes, clusters, clouds, and specialized hardware.
PhantomInference is broad enough to support multiple product architectures without losing its central association with production AI.
Managed inference infrastructure for production AI applications.
A high-performance runtime for model execution and agentic inference.
One intelligent entry point for routing inference across models and providers.
Performance, utilization, and cost optimization for inference fleets.
Private, controlled inference for sensitive enterprise workloads.
Visibility into model performance, latency, routing, and inference economics.
Because inference is powerful precisely because it is mostly invisible. The user sees an answer, classification, recommendation, prediction, image, action, or generated sequence. The computation behind it disappears.
The infrastructure is present without being exposed to the user.
Intelligence operates continuously behind production systems.
The hidden layer is built around immediate computational response.
Inference increasingly powers systems that reason and act on their own.
High-volume language-model inference behind developer-facing APIs.
Continuous image and video inference across edge or cloud infrastructure.
Low-latency speech recognition, synthesis, and conversational inference.
Real-time ranking and prediction workloads at application scale.
Inference loops that translate perception and context into physical decisions.
Repeated model calls powering reasoning, planning, tool use, and action.
PhantomInference is not tied to a particular model, hardware vendor, framework, or generation of AI.
That gives the name longevity. Models change. Accelerators change. Serving architectures change. Inference remains the fundamental mechanism through which trained intelligence becomes useful.
The brand sits at the infrastructure layer underneath all of them.
Technical precision in the second word. Brand identity in the first.
A distinctive infrastructure identity for inference systems, model serving, GPU orchestration, agentic AI, and the next generation of production intelligence.
Also available
A premium security identity for protecting, verifying and governing the high-value cache state behind modern AI inference.
A precise enterprise AI .COM for governing what AI systems retrieve, which sources enter model context, who is authorized to acces…
A premium .COM for Python execution environments, developer platforms, AI application infrastructure, cloud runtimes, and next-gen…