.com 
fabricstrategy.com
A high-authority strategy brand for designing the connective fabric across data, AI, technology, workflows, governance, operating…
ai
View listing
Home / Domains / runtimellm.com
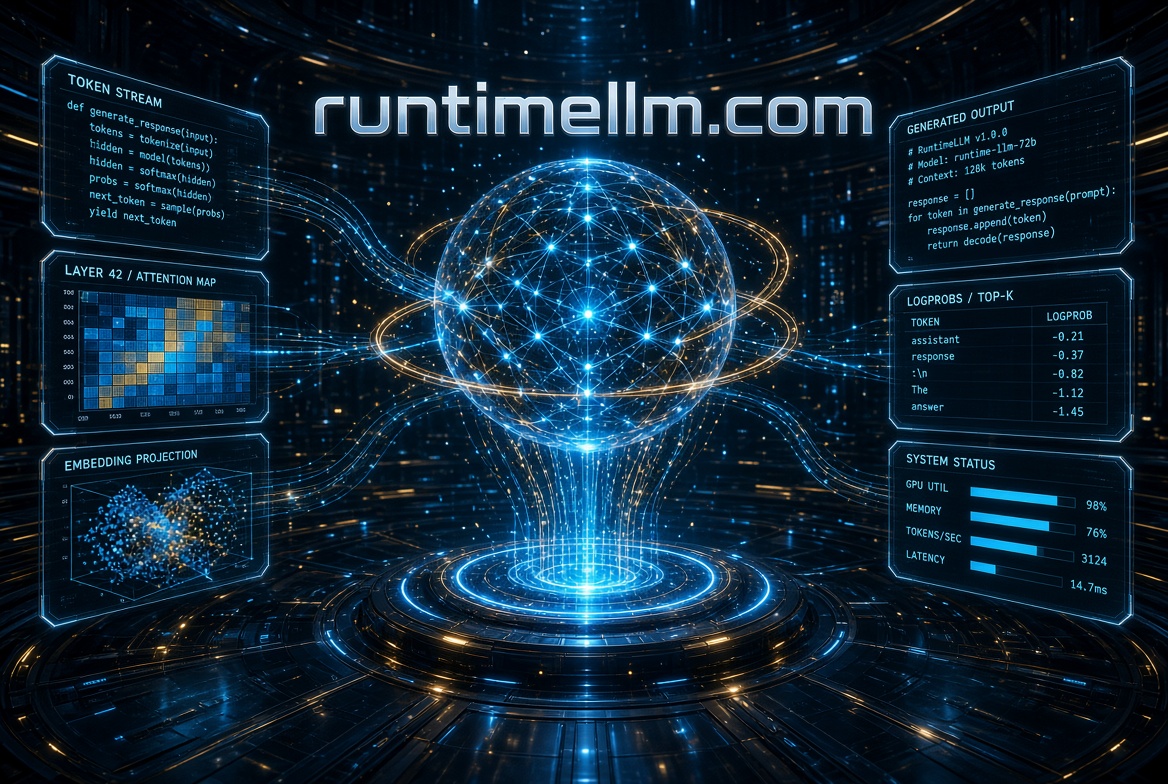
Building with large language models involves more than selecting a model and sending a prompt. Production AI applications need execution environments, efficient request handling, streaming r
One message opens the conversation — availability, price, and how the transfer works.
Inquire on WhatsAppPrivate conversation. No account, no public bidding.
Prefer a form? Send a message
About this name
FROM MODEL TO PRODUCTION.
Building with large language models involves more than selecting a model and sending a prompt. Production AI applications need execution environments, efficient request handling, streaming responses, monitoring, and reliable deployment workflows. RuntimeLLM.com is a technically direct domain concept for LLM inference infrastructure, model execution platforms, and developer tooling for production AI. By pairing the familiar engineering term runtime with the widely recognized abbreviation LLM, the name communicates a focused product category with clarity and confidence.
Running LLM workloads can involve model loading, request routing, context management, token generation, concurrency controls, and performance monitoring. A platform branded RuntimeLLM could unify these execution concerns into a developer-oriented control layer, making it easier to explore how models are deployed, observed, and managed. The concept is particularly suited to a product centered on the operational layer between model capability and application delivery.
Conceptualize model execution and token generation.
Explore workload distribution across model endpoints.
Visualize latency, throughput, and execution traces.
Imagine configuration and lifecycle management tools.
The model execution pipeline, token throughput, latency values, trace curves, and runtime states are fictional interface examples. They are not measured benchmarks, actual model-serving results, verified infrastructure capabilities, live operational telemetry, or claims that a RuntimeLLM product exists.
RuntimeLLM.com could anchor an LLM inference server, model-serving framework, managed AI runtime platform, deployment orchestration product, inference monitoring suite, prompt execution gateway, edge AI runtime, or developer-focused AI infrastructure company. Its appeal comes from combining a foundational software engineering term with a clearly recognizable AI workload category.
A potential identity for an LLM inference runtime, model server, execution scheduler, token-streaming engine, model-loading framework, or infrastructure platform designed around production AI workloads.
An alternative direction for inference observability, request orchestration, AI application monitoring, runtime policy controls, multi-model routing, developer dashboards, and managed model-serving workflows.
Also available
A high-authority strategy brand for designing the connective fabric across data, AI, technology, workflows, governance, operating…
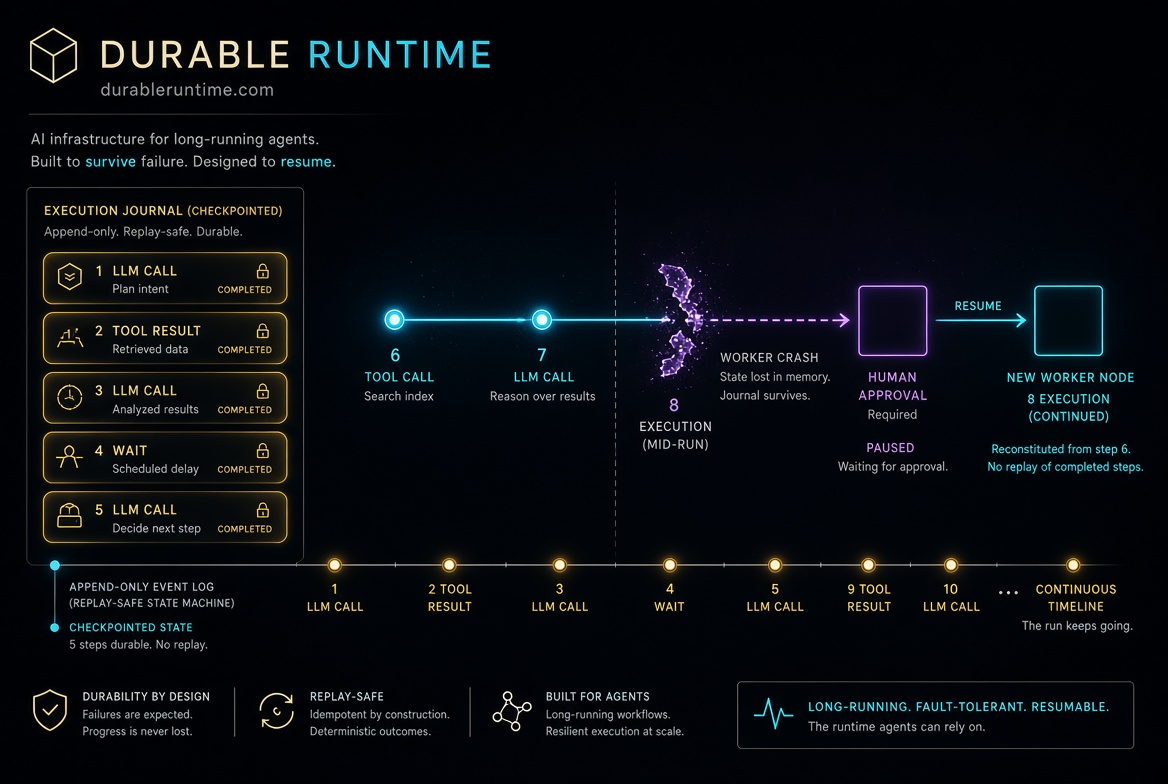
DurableRuntime.com is a category-grade .com for infrastructure that keeps AI agents, autonomous workflows, and long-running proces…
A category-defining infrastructure identity for the optical backbone connecting accelerators, racks, clusters and AI factories at…